Methodology
This page documents the numerical machinery behind Magνs: the Magnus expansion itself, the two families of integrators, the guarantees they carry, the adaptive-refinement and performance engineering built around them, and the evidence used to validate all of it. See When is Magνs the right tool? on the front page for the short version.
The Magnus expansion
Neutrino flavor evolution is governed by the Schrödinger-like equation
with \(\mathbb{H}(l)\) the (possibly position-dependent) flavor Hamiltonian. The evolution operator \(\mathbb{U}(l_1, l_0)\) satisfies the same equation with \(\mathbb{U}(l_0, l_0) = \mathbb{1}\). When \(\mathbb{H}\) does not commute with itself at different positions, \(\mathbb{U}\) is not simply \(\exp\!\left[-i\int_{l_0}^{l_1} \mathbb{H}(l)\, dl\right]\).
The Magnus expansion instead writes \(\mathbb{U}(l_1, l_0) = \exp[\Omega(l_1)]\) exactly, where \(\Omega = \sum_k \Omega_k\) is built order by order from nested commutators of \(A(l) \equiv -i \mathbb{H}(l)\), by a Bernoulli-number recursion [BCOR09] written out in The recursion. Magνs implements it through \(n = 10\); since \(B_j = 0\) for odd \(j \geq 3\), only the \(j = 1\) and even-\(j\) commutator groups appear. Orders 1 to 6 are written out inline; beyond that, the terms are generated from the recursion, since their number roughly doubles per order. Magnus expansion terms to any order derives them symbolically at any order, and the test suite checks every term against that derivation (see Validation strategy).
A truncated series still gives a unitary evolution operator. Whatever order the sum stops at, \(\Omega\) remains anti-Hermitian, since each \(\Omega_k\) is a real combination of nested commutators of anti-Hermitian matrices. Hence, \(\exp(\Omega)\) is unitary for any truncation order and quadrature accuracy. In floating point, it is unitary to round-off. One exponential deviates by \(\lVert \mathbb{U}^\dagger \mathbb{U} - \mathbb{1}\rVert = 4\times10^{-16}\) in the median (the worst of a stack of 4096 reaches \(4\times10^{-15}\)). The full evolution operator behind one probability, a product of many such factors, deviates by \(3\times10^{-12}\) to \(1.6\times10^{-11}\) at worst across four decades in the number of points, at two to five flavors. This is the central practical advantage over direct ODE integration, whose iterates only approximately preserve unitarity.
The series converges absolutely whenever
\(\int_{l_0}^{l_1} \lVert A(l)\rVert_2\, dl < \pi\) over the interval
in question. Magνs partitions the trajectory into a chain of slabs and
evaluates the expansion independently in each one; a large accumulated
phase (a long baseline, a strong potential or both) is handled by adding
more, narrower slabs rather than by raising the expansion order. Magνs
checks \(\lVert\Omega\rVert_2\) on every slab, from the spectrum
already computed for the matrix exponential (see below), and emits
MagnusConvergenceWarning when it reaches \(\pi\) on some slab. The
sufficient condition for convergence is then not met; this alone says
nothing about the error.
Two integration methods
Evaluating the nested integrals of the expansion requires sampling \(A(l)\) inside
each slab. Magνs offers two families, selected via
integration_method, which defaults to 'gl':
Gauss–Legendre collocation integrators ('gl', the default).
Following Blanes et al. [BCR00] and Blanes et al. [BCR02], orders 2, 4, 6 and 8
can be reached from only 1, 2, 3 or 4 evaluations of \(A\) per slab, at the
Gauss–Legendre nodes,
with no cumulative quadrature and no separate commutator bookkeeping:
with \(h\) the slab width and \(A_i\) the Hamiltonian sampled at the corresponding node. Because the quadrature order matches the truncation order, this method needs far fewer Hamiltonian evaluations for the same accuracy. It is the default because it is both the fastest and the most accurate method when the Hamiltonian is smooth within a slab. Slab edges at the layer boundaries (below) ensure this smoothness even across the Earth.
Orders 4, 6 and 8 need 1, 3 and 6 commutators, the fewest possible at each order [BCR02]; the Magνs paper lists the coefficients of the order-6 and order-8 schemes. No collocation scheme of this form is known at order 10 or above.
Because 'gl' uses a fixed 1, 2, 3 or 4 nodes per slab, accuracy is controlled
by the slab count alone, and the adaptive refinement below grows only n_slabs.
The four points-per-slab settings (n_tpts_per_slab, min_n_tpts_per_slab,
max_n_tpts_per_slab, growth_factor_n_tpts_per_slab) are ignored with
'gl'; passing one emits IgnoredQuadratureSettingWarning,
and the result is the same as without it.
With 'gl', the adaptive refinement ladder (see Adaptive refinement and slab placement) always
starts from a slab count estimated from the accumulated phase. The quadrature methods
depend on both n_slabs and n_tpts_per_slab, so their per-point ladder does not use
that estimate.
Their energy-batched scan uses it only when it is at least
magnus.oscprob.QUADRATURE_SEED_MIN_SLABS (4) slabs: in measurements, a
smaller starting count could add a refinement level, and a larger one never did.
Cumulative quadrature ('trapezoid', 'simpson'). Sample \(A\) on a
uniform grid of n_tpts_per_slab points and integrate with cumulative trapezoid or Simpson’s
rule. These methods are slower for the same accuracy on a smooth profile, but they are fully
general and accept magnus_exp_order up to 10. A kink or a discontinuity belongs on a slab
edge, declared with t_breakpoints: there, each slab takes its endpoint sample immediately
inside itself, so both sides of a jump are integrated with their own values and the rule keeps
its order. A discontinuity left inside a slab degrades every method. The quadrature error
(\(O(h^2)\) or \(O(h^4)\) in the grid spacing \(h\)) can dominate the Magnus
truncation error at high orders unless n_tpts_per_slab grows accordingly. The grid starts
at 100 points per slab, and the refinement grows it together with the number of slabs.
What magnus_exp_order means on each path. On 'gl', it is the order the method
delivers: the error over the trajectory falls as \(h^p\), or
\(N_{\rm slabs}^{-p}\), with \(p\) = magnus_exp_order. On 'simpson' and
'trapezoid', it is the index of the last \(\Omega_k\) kept, and the order delivered runs
ahead of it, \(2\lfloor k/2 \rfloor + 2\): order 6 on Simpson keeps \(\Omega_1\) through
\(\Omega_6\), including both \(\Omega_5\) and \(\Omega_6\), and is an eighth-order
method. Every delivered order is even, because about the slab midpoint each
\(\Omega_k\) carries only odd powers of \(h\), which pairs the terms
(\(\Omega_3\) and \(\Omega_4\) both at \(h^5\), and so on). An odd request raises
ValueError on 'gl', which has even schemes only. On the cumulative rules, it
delivers the same order as the even request below it, at the cost of one more term:
|
|
|
|
|---|---|---|---|
1 |
ValueError |
2 |
|
2 |
2 |
4 |
|
3 |
ValueError |
4 |
|
4 (default) |
4 |
6 |
|
5 |
ValueError |
6 |
|
6 |
6 |
8 |
|
7 |
ValueError |
||
8 |
8 |
10 |
|
9 |
ValueError |
||
10 |
ValueError |
12 |
Entries without parentheses are measured: the error relative to DOP853 on a smooth,
non-commuting problem is fitted against the slab count. Entries in parentheses follow from the
two rules above. ValueError marks a request 'gl' refuses.
Unitarity from the spectral decomposition
Since \(\Omega\) is anti-Hermitian, Magνs computes \(\exp(\Omega)\) from the eigendecomposition of the Hermitian matrix \(K = i\Omega\):
This is faster than a general (Padé-based) matrix exponential for stacks of small matrices, and
unitary to round-off (\(\mathbb{U}^\dagger \mathbb{U} - \mathbb{1}\) of order 1e-15; see
Performance). By default (EXPM_BACKEND = 'auto'), the spectrum comes from compiled
kernels — Cayley–Hamilton for 2×2 and 3×3, batched Jacobi for 4×4 and 5×5 — and from
numpy.linalg.eigh otherwise. A general (non-anti-Hermitian) fallback based on
scipy.linalg.expm is available for exotic, non-physical uses of the underlying
magnus.magnus.magnus_expansion() engine.
Time-ordering
A neutrino traversing a chain of slabs accumulates the evolution operator as a time-ordered product, with the last slab as the leftmost factor:
This matters physically whenever the Hamiltonians of different slabs do not commute, e.g., any two slabs of different density, since the matter potential does not commute with the vacuum Hamiltonian. The test suite exercises it directly with an exact two-constant-slab check (\(\exp(-iH_B L_2)\exp(-iH_A L_1)\) from matrix arithmetic alone, no quadrature).
Adaptive refinement and slab placement
By default, osc_prob and its wrappers refine the number of slabs (and, for the quadrature
methods, the number of points per slab) until the probability matrix stops changing within a
requested tolerance (rtol, atol). Each step multiplies the slab count by 1.5
(growth_factor_n_slabs) and recomputes. The ladder stops when two successive levels agree
in every entry:
strict_convergence=True asks for two consecutive agreements instead of one. Declared edges
are present at every level, so they can shrink the step between two grids; an agreement counts
only when the finer grid has at least 25% more edges than the coarser one. Every level below
the one that converges is computed and discarded: on an Earth chord, this makes a call three to
four times slower than one given the right slab count. convergence_info reports that count,
and passing it as n_slabs with rtol=atol=None reuses it. Four mechanisms keep the
ladder short:
A starting slab count from the accumulated phase. Rather than starting from one slab, the refinement starts from an estimate of the accumulated (traceless) phase \(\lVert\Omega_1\rVert_2\) over the whole trajectory. It aims for roughly \(2\pi\) radians of phase per slab, enough for the Gauss–Legendre method to be close to converged at the first level. This seed is deliberately looser than the convergence bound of \(\pi\), because the refinement loop, not the bound, decides the accuracy. As a result,
MagnusConvergenceWarningcan be emitted for a coarse level below the returned one, even when the returned answer meets the tolerance.Warm starts across scan points. When computing many points (an energy scan, an oscillogram), each point’s refinement is seeded from the previous point’s converged slab count and point count, rather than from the bottom of the ladder.
Slab edges aligned with density discontinuities. The PREM profile used for the Earth is piecewise-smooth, with density discontinuities at the boundaries between its ten shells [DA81a]. A slab that straddles one of these boundaries locally degrades the quadrature to low order no matter how high
magnus_exp_orderis set. The Earth wrappers compute the exact chord positions where the trajectory crosses a PREM layer boundary (roots of a quadratic whose coefficients depend on the zenith angle) and insert them as mandatory slab edges at every refinement level.A floor set by the user. Passing
n_slabstogether with a tolerance sets a lower bound on the ladder: refinement starts atmax(min_n_slabs, n_slabs)and only ever climbs from there (clipped atmax_n_slabs). With the defaultn_slabs = 1, the floor is inactive.
Warning
The phase estimate that seeds the ladder is an integral of the
Hamiltonian along the trajectory, and an integral is blind to structure
that averages out. A profile that oscillates rapidly about its mean —
a castle wall, a periodically layered medium — can accumulate very
little net phase while still demanding many slabs to resolve, and will
then be seeded with far too few. The successive-iterate test is no
protection here: refinements that all fail to see the profile can agree
with each other while disagreeing with the truth, and a tighter rtol
only compares two answers that are both wrong. The remedy is to resolve
the profile, not to tighten the tolerance.
If the feature scale of the profile is known, declare it in one of two
ways. Pass n_slabs (a floor, per the bullet above) so the ladder
cannot start below it. Better still, where the features are
discontinuities at known positions, pass those positions as
t_breakpoints: they become mandatory slab edges, which both resolve
the profile and restore the quadrature’s nominal order, and so cost less
than the equivalent number of uniform slabs. On a 50-wall castle-wall
profile, the two together reduce the worst-case error over a baseline scan from 0.855 to 1.9e-3,
while running faster than the under-resolved version did.
The slab cap itself is method-aware. max_n_slabs defaults to None,
meaning “use the cap appropriate to integration_method”: 20 000 for
'gl' and 2000 for the cumulative-quadrature methods (see
magnus.oscprob.MAX_N_SLABS_DEFAULT; an explicit value is always used as
given). The two caps differ because the cost per slab differs by more than
an order of magnitude: 'gl' evaluates the Hamiltonian 1 to 4 times per
slab, the quadrature methods n_tpts_per_slab times. 'gl' needs the
higher cap for problems such as eV-scale sterile splittings across the Earth,
which take about 8600 slabs. Even at 20 000 slabs, it is the cheaper worst
case: 40 000 Hamiltonian evaluations at the default order and 80 000 at order
8, against about 200 000 for 2000 quadrature slabs at 100 points each.
If a refinement cap (max_n_slabs, max_n_tpts_per_slab or
max_num_loops) is reached before the tolerance is met, osc_prob
returns its best estimate and always issues ToleranceNotAchievedWarning,
whatever the verbose setting. The probabilities are still unitary, so
they can look plausible while being inaccurate. This is expected for extreme
accumulated phases, such as low-energy solar neutrinos crossing most of the
Sun. There, an adiabatic treatment is the better tool:
Adiabatic + Magnus hybrid strategy describes strategy='hybrid' and 'auto', whose
local patches use the same magnus.magnus.magnus_expansion_multislab()
kernel.
Choosing the expansion order
magnus_exp_order defaults to 4, and for the tolerances most calculations
ask for, that is the right choice. The adaptive refinement already turns a
higher order into fewer slabs on its own, so the order and the requested
tolerance interact: raising the order pays only once the tolerance is tight
enough to make the extra work per slab worthwhile.
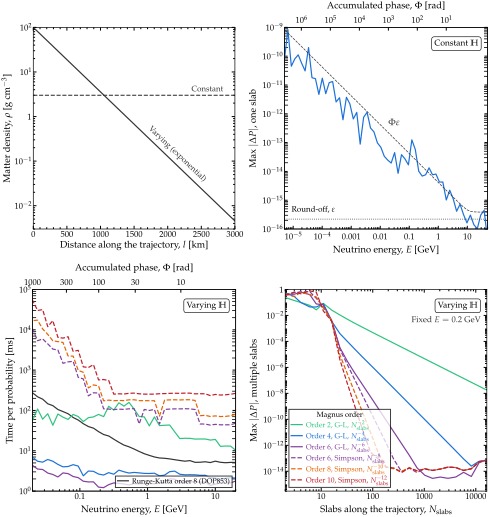
Cost and accuracy of a Magnus slab, at three flavors. Top left: the two density profiles, constant and exponential. Top right: one slab against an exact exponential of the same constant Hamiltonian; the deviation reaches a floor near machine epsilon and grows as \(\Phi\varepsilon\), with \(\Phi\) the slab phase and \(\varepsilon\) machine epsilon. Bottom left: time per probability for six Magnus configurations and for DOP853, all at a tolerance of \(10^{-8}\). Bottom right: deviation from an extended-precision reference against the number of slabs. From the Magνs paper.
Across Earth, solar and exponential density profiles, order 6 runs 0.96 to 1.12 times as fast as order 4 at a requested tolerance of \(10^{-4}\), and 1.08 to 1.93 times as fast at \(10^{-8}\), under the timing protocol of Performance.
Keep the default order for everyday work, and raise it to 6 for a tight tolerance, where it runs up to about twice as fast. Dropping to order 2 is almost never worthwhile: at \(10^{-8}\) on an Earth chord it needs thousands of slabs where order 6 needs about a hundred.
Beyond order 6, the terms are generated (see Magnus expansion terms to any order). 'gl'
reaches order 8 on its four-node scheme; orders 7, 9 and 10 exist only on
'trapezoid' and 'simpson', which warn about their cost above order 6. The
high orders serve accuracy studies rather than production runs.
Note
The defaults rest on two measurements, both against a tight-tolerance reference computed at order 6 with the slab cap raised:
Cheapest configuration sweep. The sweep covered seven cases: Earth PREM 3ν at 0.5, 1 and 10 GeV; Earth PREM 5ν; an exponential density profile; the Sun at 100 MeV; and Earth 3ν with NSI. For each case and each of the targets \(10^{-4}\), \(10^{-6}\) and \(10^{-8}\), it found the smallest slab count reaching that accuracy at orders 2, 4 and 6, with the adaptive loop switched off. Counted in Hamiltonian evaluations, the optimal order rose monotonically as the tolerance tightened, in every case.
Wall-time confirmation. Evaluation count is a poor proxy: the fixed per-slab overhead (array setup, the eigendecomposition for the matrix exponential, the slab product) outweighs the node count, so reducing the slab count matters more than reducing the evaluation count. Re-timing the same optima produced the ranges above, and it moved the crossover: order 2 wins on evaluations at \(10^{-4}\) but loses on wall time.
The starting slab count does not depend on the order. An order-aware seed, coarser for higher orders, gave no speed-up in measurements: the refinement loop sets the final count, and a coarser start only adds a refinement level on the way to it.
Vectorization and the energy-batched scan engine
Two further optimizations change no physics and need no change to user code, although the first runs faster if the Hamiltonian is written for arrays:
Hamiltonian vectorization. A user-supplied Hamiltonian or density-profile function is probed once. If it accepts an array of positions and returns a matching stack of matrices (verified against a scalar spot-check), that vectorized form is used for every subsequent evaluation. Otherwise, Magνs falls back transparently to evaluating it one point at a time. Repeated evaluations of a density profile on identical position grids (common across an energy scan, where only the vacuum term of the Hamiltonian depends on energy) are additionally cached.
The fallback gives the same answer, more slowly. The engine samples the Hamiltonian at every quadrature node of every slab, a few hundred positions for one probability at each refinement level, so a scalar-only function turns that into a Python loop. On a three-flavor exponential-density profile, making
H_funcarray-capable cut the time perosc_prob()call from 7.8 ms to 1.7 ms, with bit-identical output. The scalar fallback emitsScalarHamiltonianWarningonce per session. An array-capable function must still return a single(d, d)matrix when given a scalar, which the probe checks. A Hamiltonian that ignores its argument is detected separately and broadcast. The wrappers already build array-capable Hamiltonians. Writing an H_func that takes many positions at once shows how to write one.Energy-batched scans. The standard, NSI and LIV Hamiltonians all have the separable form \(\mathbb{H}(E, l) = \mathbb{H}_E(E) + V_{\rm CC}(l)\, M\), with \(\mathbb{H}_E\) collecting the energy-dependent (vacuum and LIV) terms and \(M\) a fixed matrix. When many energies share a single baseline, Magνs runs the entire scan as one batched computation. The potential is sampled once per refinement level and shared across all energies. The quadrature, commutators, matrix exponentials and slab products carry the energy as an extra array dimension, and energies that have converged are not recomputed.
Validation strategy
The test suite, which runs in CI on every push (see the badge on Magνs: neutrino oscillations via the Magnus expansion), validates the methodology above directly:
The expansion terms \(\Omega_1, \ldots, \Omega_{10}\) are compared, term by term, to the terms Magnus expansion terms to any order derives independently from the recursion, using a Hamiltonian with three independent, non-commuting generators. Three generators are needed because with two, one nested-commutator term of \(\Omega_4\) vanishes identically and would mask a coefficient error.
Convergence order is checked against a high-accuracy
scipy.integrate.solve_ivp(DOP853,rtol=1e-12) solution of the same Schrödinger equation, confirming that each additional Magnus order reduces the error. The same check confirms that the Gauss–Legendre integrators achieve their nominal orders 2, 4 and 6 (measured error reduction ratios of 4.0, 16.0 and 63.8 under slab halving, matching \(2^{\text{order}}\)); the order-8 scheme is not part of this rate check.Physical probabilities are cross-checked against closed-form expressions for 2ν and 3ν vacuum oscillations and 2ν constant-density matter oscillations (for both neutrinos and antineutrinos), to \(10^{-12}\), and against
solve_ivpfor asymmetric, complex-valued profiles and for full PREM Earth crossings.Time-ordering, unitarity, channel conventions, the vectorization path and its scalar fallback, and the energy-batched scan each have dedicated regression tests, including a pure matrix-arithmetic check (no quadrature) that isolates the slab time-ordering from every other source of numerical error.
In practice, the default setting (rtol = atol = 1e-3, a stopping rule rather than a bound)
is usually far more accurate than the tolerance suggests. In the rare cases where it is not,
the error stays within about three times the tolerance over the populations that
Accuracy and diagnostics reports, scored against an independent reference. Over eight Earth chords,
from grazing to core-crossing, at six energies between 0.5 and 20 GeV, the difference from the
same call at \(10^{-7}\) is about \(10^{-6}\) in the median and below \(10^{-4}\)
in nine cases in ten. At most, it is about \(10^{-3}\), on the core-crossing chord at 0.5
GeV.
See References for full citations of the works referred to above.
The conventions — flavor order, signs, the mass ordering, the parameters and the units — are on their own page, Conventions.